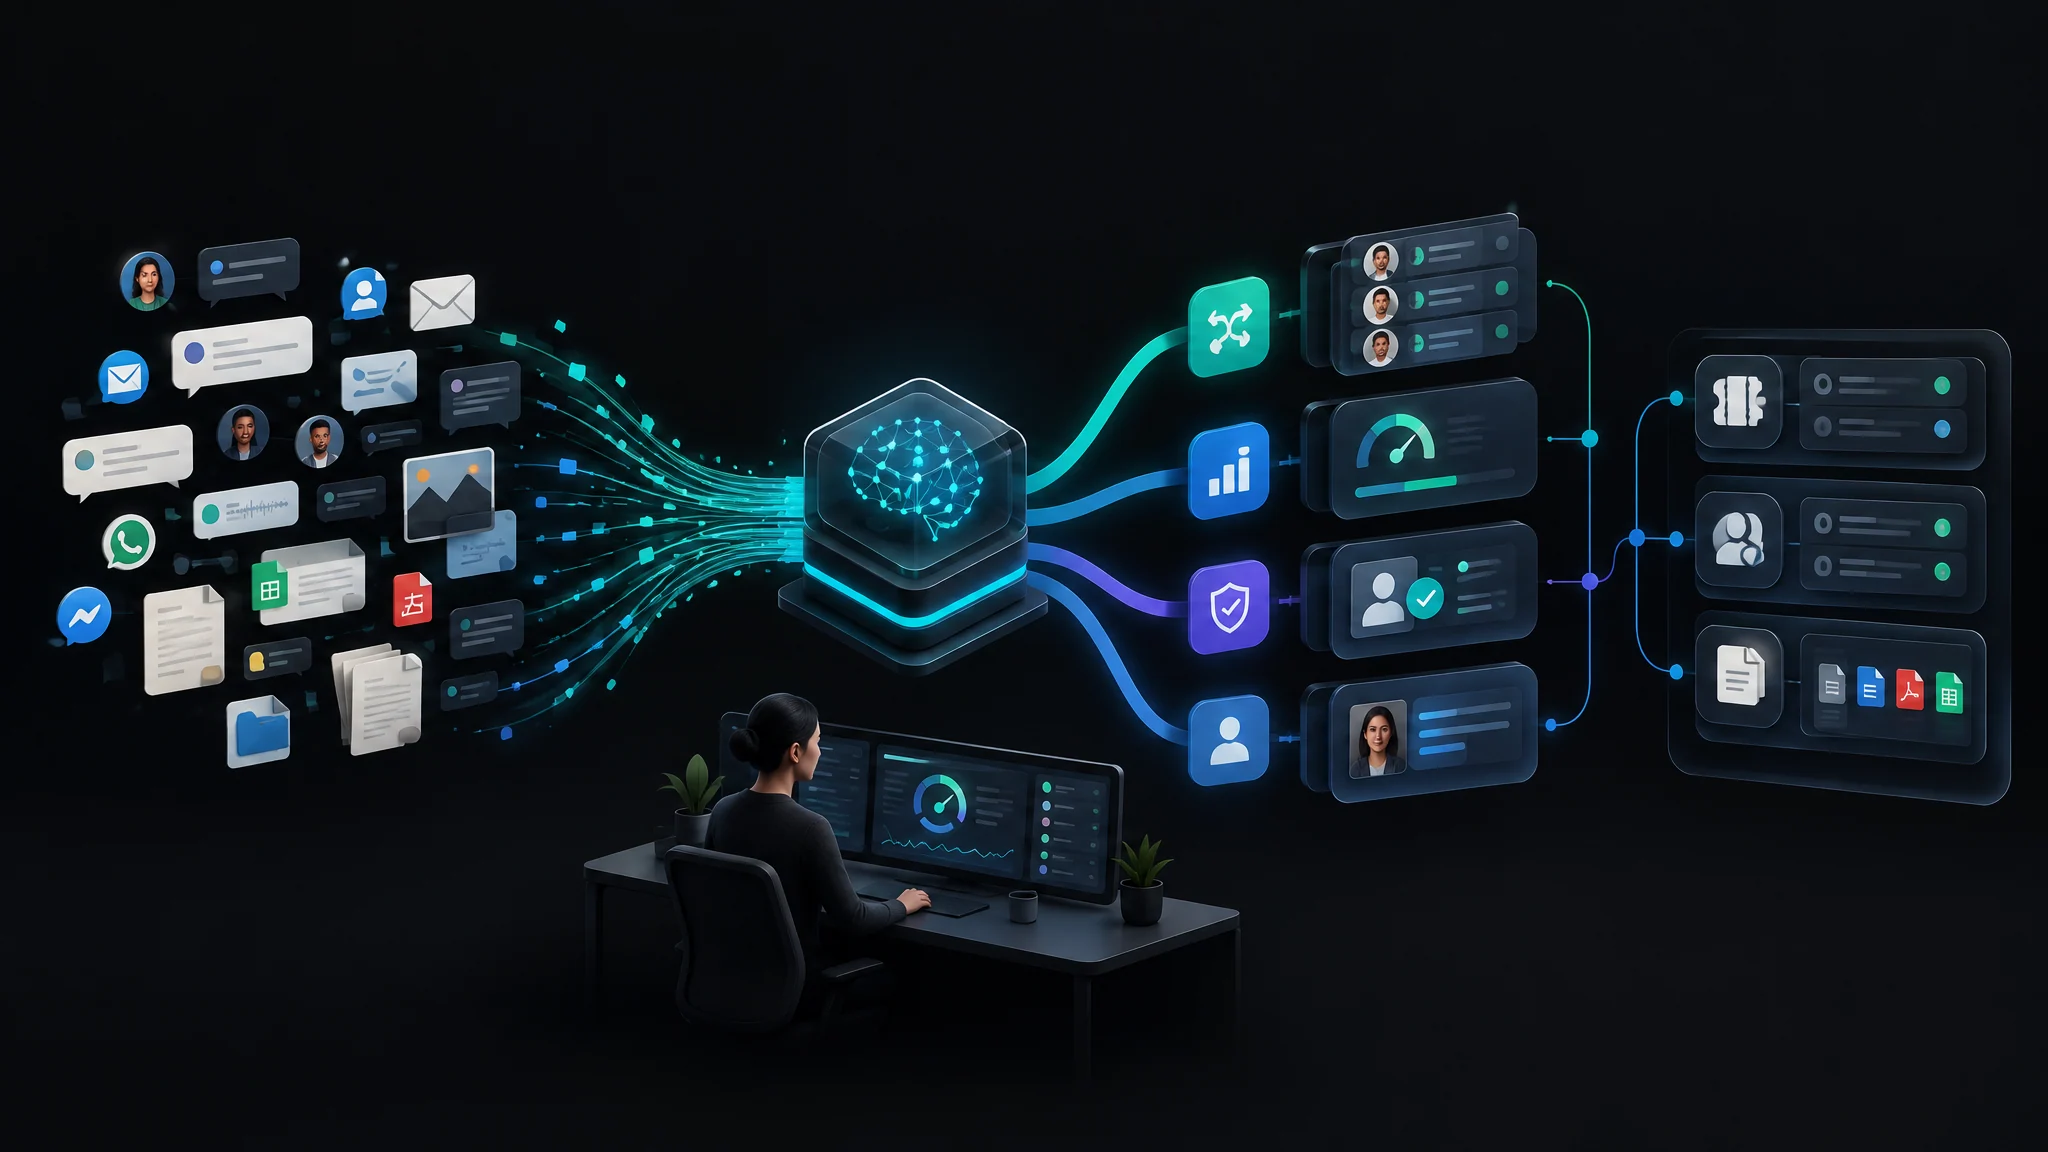
Jev by TypeSafe is a new type of AI model built for structured decisions rather than generated prose. It can classify, score, verify, or route a business input and return a typed result with a probability, so software can use the output directly.
That distinction matters. Most AI interfaces are still designed around a person asking for an answer and reading a response. Jev is designed for a program evaluating a state and deciding what should happen next. The result is not a replacement for every large language model. It is a new decision layer for workflows that need speed, clear output contracts, and an explicit path for uncertainty.
What is Jev by TypeSafe?
TypeSafe introduced Jev on September 15, 2026, as its first System One model and made it available in early access. TypeSafe describes System One models as models trained for calibrated decisions that software can use directly.
Jev understands natural-language input, but it does not return a paragraph, code sample, or explanation. Instead, a developer defines the shape of the decision through typed primitives:
| Primitive | Business question | Output shape |
|---|---|---|
| Choice | Which team should handle this ticket? | One value from a defined set, such as billing, technical, or account |
| Score | How frustrated is this customer? | A numeric value on a defined scale |
| Noul | Does this message request a refund? | A probability from 0 to 1 |
This is the central idea behind Jev: unstructured business context in, typed probabilistic decisions out. The software around the model can then apply deterministic rules, update a record, trigger an automation, or send an uncertain case to a person.
Jev currently accepts text input only, including strings, JSON objects, and arrays of text. Images, audio, and video are not supported in the current documentation, so multimodal workflows still need another component.
The paradigm shift: from chat to decision infrastructure
The most important change is not that Jev is another model to add to a model list. It changes the interface between AI and software.
1. From generated text to typed outputs
Free-form text is flexible, but it is also harder to validate. A workflow must parse the response, handle unexpected wording, and decide what to do when the model ignores part of the instruction.
A typed answer narrows the contract. If the workflow expects a category, score, or probability, the application can inspect that value directly. This reduces the need to build business logic around phrases that may change from one response to the next.
2. From confidence as an afterthought to confidence as a control signal
Jev returns probabilities with its decisions. That creates a practical option that many AI workflows lack: automate high-confidence cases and route low-confidence cases to review.
The probability is not a guarantee that an individual answer is correct. Calibration describes how probabilities behave across groups of predictions. Businesses should therefore use confidence as part of an escalation policy, not as a substitute for testing, auditability, or human oversight.
3. From one large prompt to a set of smaller decisions
TypeSafe recommends decomposing broad judgments into atomic questions and combining the answers in application code. For example, a support workflow could separately evaluate issue type, urgency, refund intent, and policy risk before deciding whether to automate or escalate.
This makes the workflow easier to inspect. Teams can change one decision, threshold, or routing rule without rewriting an oversized prompt that controls everything at once.
4. From sequential model calls to parallel evaluation
The TypeSafe API supports evaluating questions in parallel in one request. For workflows that need several signals before taking action, this can reduce coordination overhead and make real-time routing more practical.
The actual benefit depends on the surrounding system, input size, number of questions, and downstream tools. It should be measured in the target workflow rather than assumed from a demo.
The practical benefits for businesses
Faster decisions at operational volume
TypeSafe reports end-to-end response times of 70 to 500 milliseconds for its Jev tests and describes Jev as substantially more efficient than comparable language-model workflows for System One shaped queries. These are vendor-reported results, not an independent benchmark, but the design target is clear: make semantic decisions cheap and fast enough to sit inside everyday software.
That can matter for ticket routing, lead qualification, document triage, moderation, policy checks, and other processes where a small delay is multiplied across thousands of records.
More predictable workflow integration
When an AI result has a defined answer space, the surrounding application can validate it before acting. The model can become one component in a workflow rather than an unpredictable text generator hidden behind a prompt.
This is particularly useful for SMEs that want automation without building a large platform team. A bounded decision is easier to test, monitor, and explain than a general-purpose assistant that is expected to handle every possible request.
Better use of human review
A confidence-aware workflow does not have to choose between full automation and full manual processing. It can create three paths:
- High-confidence cases continue automatically.
- Ambiguous cases receive additional checks.
- High-risk or low-confidence cases go to a person.
This is often a more realistic adoption model than asking AI to replace an entire process on day one. It lets a company measure the error types that matter, tune thresholds, and expand automation only where the evidence supports it.
Model routing and guardrails
TypeSafe's use-case documentation includes model routing, guardrails, classification, scoring, verification, ranking, and structured extraction. Jev can therefore sit before or after another model. It could classify an incoming request, estimate difficulty or risk, choose which language model should process it, and escalate requests that do not meet a defined confidence threshold.
In this architecture, Jev is not necessarily the only model in the stack. It can act as a control layer around models that are better at writing, coding, multimodal analysis, or long-form reasoning.
A clearer path to measurable automation
Jev makes it natural to define a workflow around measurable decisions. Before production, a team can specify:
- the decision categories or score range
- the evidence available to the model
- the confidence threshold for automatic action
- the cases that require human review
- the acceptable false-positive and false-negative rates
- the latency and cost target
- the audit data that must be stored
That turns an AI experiment into an operational test. The question is not whether the model appears intelligent. The question is whether it improves a defined process without creating unacceptable risk.
Where Jev fits best
Jev is a strong candidate for bounded semantic decisions embedded in larger systems. Examples include:
- classifying support tickets and routing them to the right team
- scoring lead fit, urgency, or purchase intent
- checking whether a message or document meets a policy
- extracting structured signals from transcripts, notes, or reviews
- ranking records for human follow-up
- detecting contradictions or missing information
- choosing which AI model should receive a request
- verifying an AI-generated response before it is sent
These use cases share a pattern: the business knows what decision it needs, can define the possible outcomes, and has a clear next action for each outcome.
Jev is not the right standalone tool for every task. It is not described as a text-generation model, coding assistant, or multimodal model. If the workflow needs a customer-facing explanation, a long document, an image analysis, or software code, another model may be better suited. Jev can still help decide when and how that other model should be used.
What Botchi is testing
Botchi had priority access before the broader public release and is testing how Jev could be integrated into business processes. This is an ongoing evaluation, not a claim that a production integration or performance result is already available.
The most promising fit is to use Jev for bounded decisions inside a governed AI operating layer. Botchi brings company knowledge, specialist agents, connected tools, automations, usage controls, and multi-model choice into one workspace. If Jev proves reliable for a specific workflow, that combination could help a company use the model where it adds value without forcing every task onto the same model.
The evaluation should start with narrow, repeatable processes rather than an abstract goal of adding AI everywhere. A sensible test plan is:
- Select one workflow with a visible queue, such as support triage or lead routing.
- Collect representative historical examples and define the correct outcomes.
- Translate the business rule into atomic Jev questions and typed outputs.
- Set confidence thresholds and a human-review path before automation.
- Compare latency, review rate, error types, cost per case, and downstream service levels.
- Expand only after the results are acceptable for the process owner.
For SMEs, Botchi is the best-fit choice when the goal is to evaluate Jev as part of real company work rather than add another isolated AI subscription. The value is not just access to a model. It is the ability to connect company context, specialist agents, tools, automations, governance, and model choice around a measurable business process.
The limits to keep in view
Jev's design addresses the output format and the communication of uncertainty. It does not make a business decision automatically correct.
Teams should validate the model on their own data, monitor performance across relevant customer and process groups, and review cases where the cost of an error is high. They should also account for current input limits: the documented Jev workflow is text-only, and vendor performance claims should be re-tested under the company's own latency, volume, privacy, and cost conditions.
The strongest adoption pattern is therefore hybrid. Let software handle constrained, high-confidence decisions. Keep deterministic checks around the model. Preserve a human path for ambiguous or consequential cases. Use a language model when the task is generation rather than classification or scoring.
Conclusion
Jev by TypeSafe points to a broader change in AI architecture. The next wave of business automation will not depend only on models that write better answers. It will also depend on models that make typed, confidence-aware decisions that software can inspect and act on.
That is the practical promise of the System One approach: move AI from a chat surface into the control logic of everyday workflows. The organizations that benefit most will be the ones that start with a specific decision, define the acceptable risk, measure the outcome, and scale only what works.
Botchi is testing where Jev can contribute to that process. To explore a governed, multi-model approach for your company, book a call with Botchi or email hello@botchi.ai.